Comparison of LLMs Interpretation of Medical Imaging versus Radiology Residents with Regards to Accuracy of Diagnostic Skills.
Background: The use of artificial intelligence in the medical field has become increasingly useful. AI programs are applied in diagnostic radiology for disease recognition, screening and early detection of medical emergencies. While current literature suggests that senior radiologists typically outperform AI models, it remains unclear how AI compares to radiology residents.
Objectives: This study aims to compare radiological diagnostic accuracy of widely available LLM models (ChatGPT 5.5 high, Gemini 3.1 Pro, Claude SONNET 5) to that of radiology residents at different stages of training.
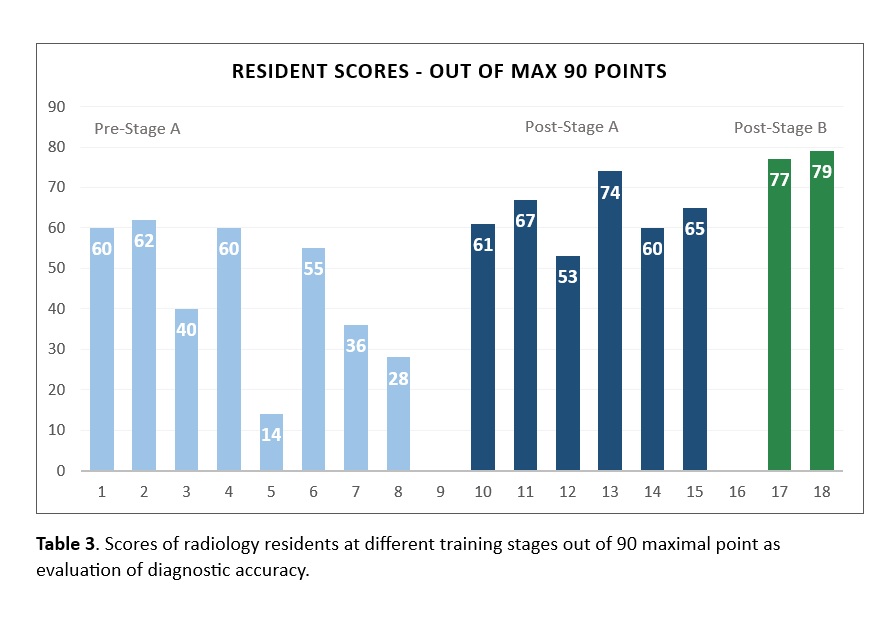
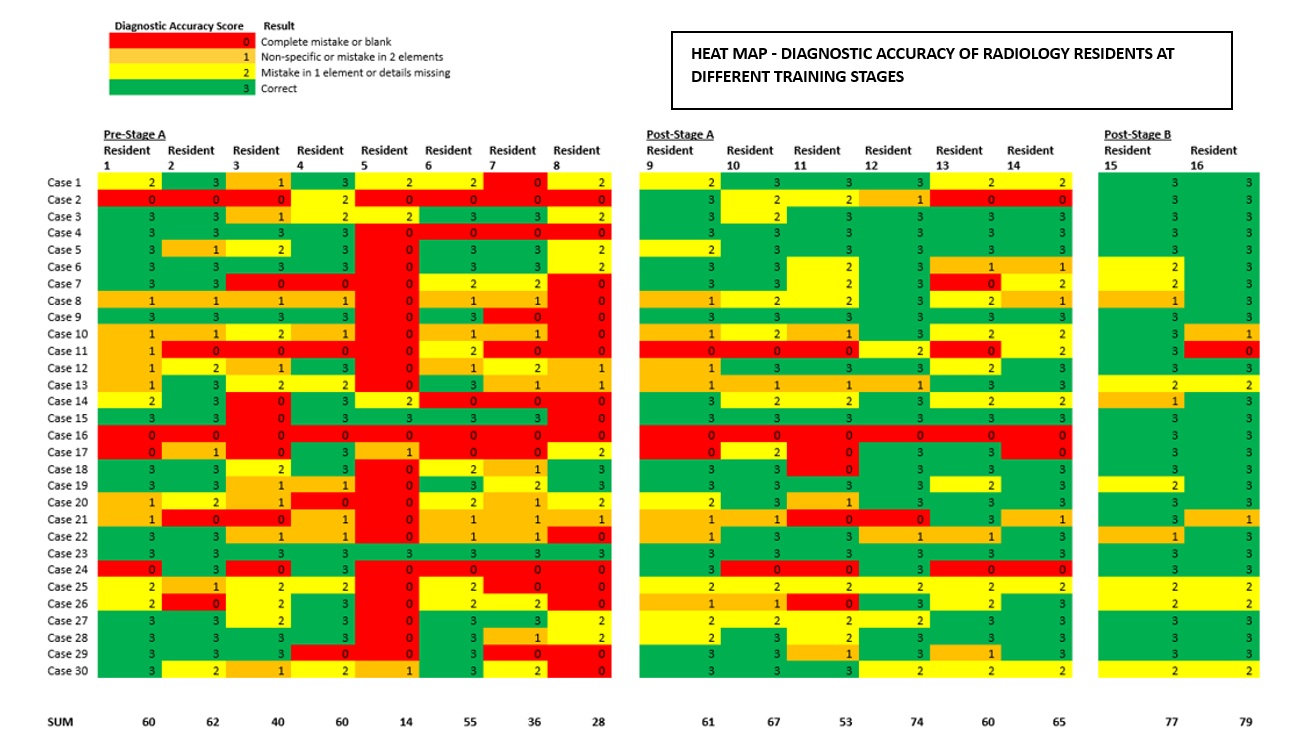
Methodology: Retrospective X-ray/CT/MRI images from 30 cases of various complexity were independently interpreted by LLM models and by radiology residents at different training stages (‘Pre-Stage-A’, ‘Post-Stage-A’, ‘Post-Stage-B’ – relative to national board examinations). No clinical context was given, however LLM engines evaluated images both with and without role prompting. All interpretations were compared to a benchmark defined by senior radiologists and a scoring system was established to evaluate accuracy of interpretation.
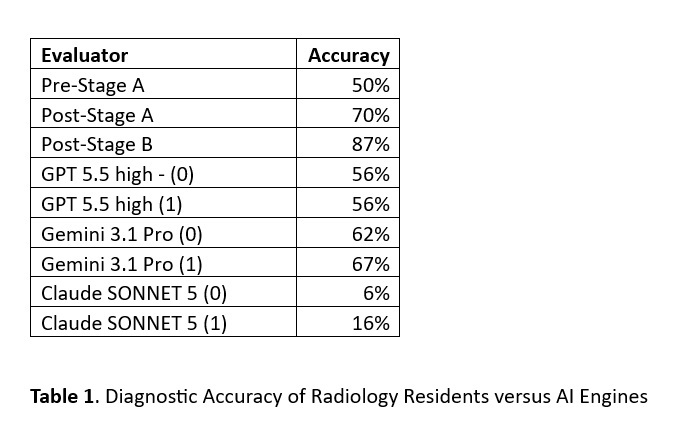
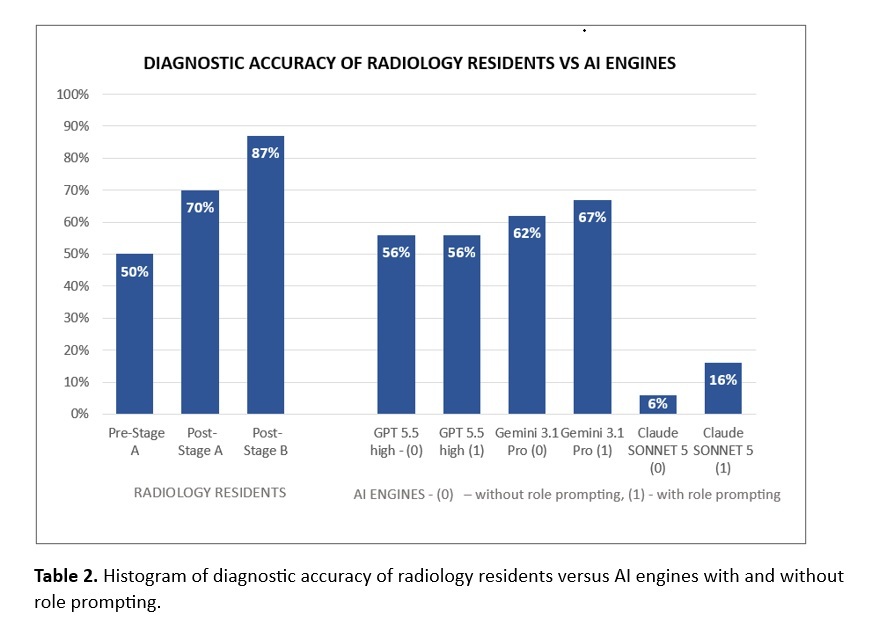
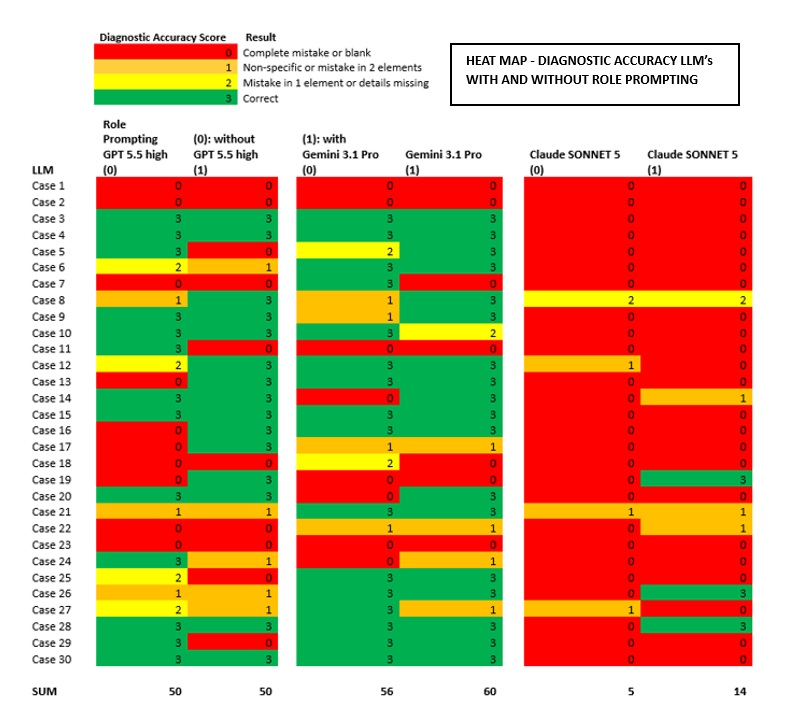
Results: The average scores of residents ‘Pre-Stage-A’, ‘Post- Stage-A’ and ‘Post-Stage-B’ were 50%, 70% and 87%, respectively. LLM engines without role prompting generated scores as follows, ChatGPT 5.5 high - 56%, Gemini 3.1 Pro – 62%, Claude SONNET 5 – 16%. The same LLM engines with role prompting achieved scores of 56%, 67% and 16% respectively.
Conclusions: As expected, diagnostic accuracy of residents was higher at more advanced stages given both increased theoretical knowledge and interpreting experience. Residents Post-Stage-A and Post-Stage-B achieved superior average results than all LLM engines. Pre-Stage-A residents achieved lower average scores than ChatGPT and Gemini, but higher average scores compared to Claude. Between LLM engines Gemini generated the highest average scores with and without role prompting. ChatGPT achieved slightly lower scores, while Claude generated significantly lower scores compared to all groups. Role prompting slightly increased accuracy in all 3 engines.